
Natural language, the language we humans use to communicate with each other, is flexible, ambiguous, and remarkably resistant to error. At the same time, our linguistic competence allows us to interpret variations, discard ambiguities, and reconstruct the meaning of a message even when it is not perfectly expressed.
A machine doesn't interpret language the way a person does. Although current models have greatly improved their tolerance for ambiguity and error, they still rely on patterns, available context, and explicit instructions. Any undergraduate or graduate student who works, even tangentially, with computers learns a painful truth in their first few months: machines are extremely literal. A misplaced comma, a misspelled word, or a phantom tab can bring a project to a standstill.
However, here we are, talking about generative artificial intelligence (AI). A giant leap in machines' ability to understand the nuanced language of humans. The question, therefore, is self-evident: does artificial intelligence work well? The answer, unfortunately, is not so obvious.
To begin with, what does it mean for an AI system to "work well"? The answer depends on our expectations. Studies They demonstrate that we treat conversational agents as if they were friends, confidants, salespeople, teachers, guides, or managers. Generative AI is no longer just writing texts or generating images: it's having a real impact on customer service processes, document analysis, internal support, and even decision-making. The data confirms this shift in scale. According to the latest global report from McKinsey Regarding the state of AI, 881% of surveyed organizations claim to use AI regularly in at least one business function, compared to 781% the previous year.
Therefore, it is no longer enough to ask if the model responds well. We need to put on the table all the qualities we expect from our AI in a specific context and verify if its responses, in context and incorporated into a process, are optimal.
Generative AI no longer lives in the laboratory
It's been a while since the first demonstrations of the capabilities of new technologies. Those early tests failed, but they were inconsequential and even amusing failures because they occurred in an experimental environment.
Now the situation has changed. Models connect to internal documents, databases, files, customer histories, and corporate tools. They no longer just produce a sentence: they can guide a claim, summarize a legal situation, and classify a case. And behind every claim, file, or case, there isn't just a piece of data: there's a person who expects a fair response, a clear explanation, and a well-founded decision.
Therefore, the nature of error changes. A wrong response in an experiment, in a controlled environment, is a technical failure; a wrong response within a critical process can become an operational, legal, reputational, or human risk.
Good metrics do not guarantee good decisions
It is therefore time to systematize an evaluation methodology for generative AI models. In a critical process, such as those described above, simply delivering good average results is insufficient: each case represents a potential legal, security, or reputational risk. Edge cases are precisely those that must be carefully considered and prevented: ambiguity, incomplete information. A model may provide a factually correct answer, but be biased, difficult to audit, or unsuitable for the recipient. It may also offer a formally appealing answer, but generate confusion, frustration, or a false sense of certainty in the user. Technical metrics remain useful, but they do not encompass all the information a company needs before integrating an AI agent into processes that affect its security, reputation, or regulatory compliance, and that could negatively impact people, whether or not they are users of the AI agent.
Evaluate the system, not just the model
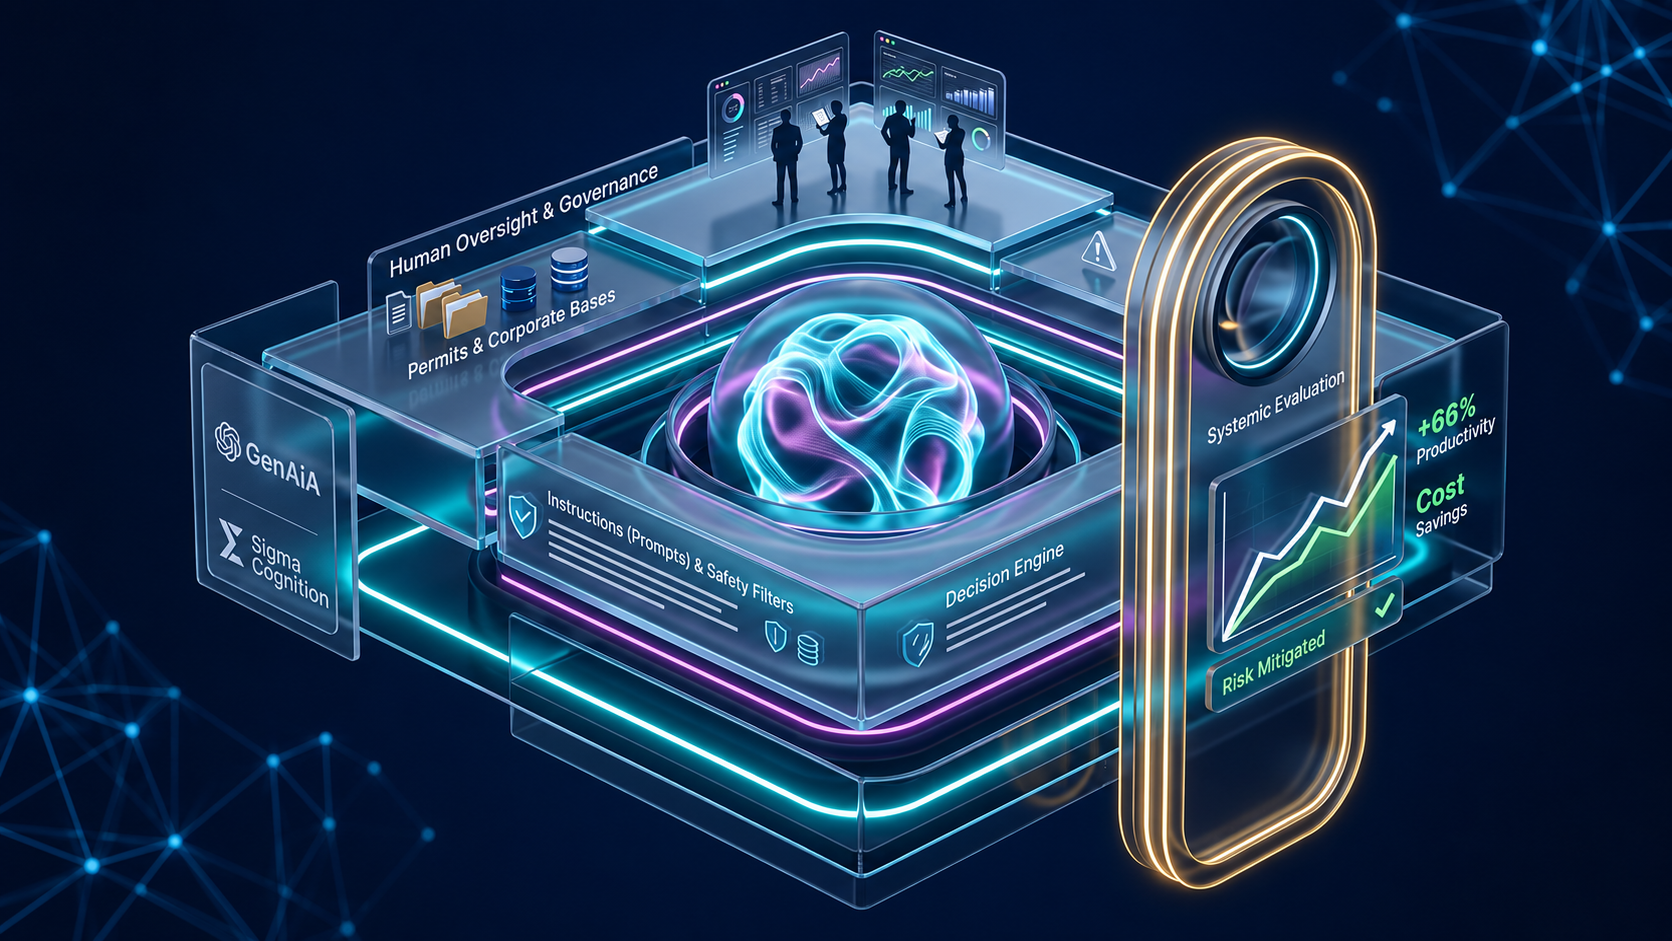
When a company incorporates generative AI into a real-world process, it's not just deploying a model. What comes into play is a complete architecture: instructions, documentation, permissions, external tools, and human oversight. Failures can occur at any of these points. Therefore, evaluating generative AI cannot consist solely of assessing isolated responses; it must shift from the isolated performance of the model to the governance of the entire system.
The consequence is that there is no universally valid evaluation for any generative model. A system may be perfectly capable of summarizing internal documentation and, at the same time, inadequate for handling a complaint. The relevant question ceases to be whether the model is "good" in general terms and becomes whether it is suitable for a specific function, under known conditions and with an explicitly assumed margin of error.
From promising technology to decision infrastructure
The decisive leap involves moving beyond asking whether AI works in the abstract and starting to measure whether it works for a specific use, also taking into account its impact on people. Its adoption is already generating tangible business results: among the companies adopting AI agents, PwC It notes that the 66% delivers productivity increases, the 57% cost savings, the 55% faster decision-making, and the 54% improvements in customer experience. Precisely for this reason, the greater its potential impact, the more important it is to evaluate its reliability, traceability, and suitability for the context before integrating it into critical processes, keeping in mind that this evaluation must ensure that this technology serves people and safeguards their safety.
Before entering a critical process, a generative model must demonstrate what that process requires: accuracy in some cases, prudence in others, traceability, bias control, data protection, security, explainability, and human oversight. There is no single assessment that works for all models or all companies. The key is to define which risks are relevant in each context and translate them into measurable evidence.
At Sigma Cognition, as a member of GenAiA, we advocate for a flexible evaluation, adapted to each organization, each model and each use case, based on evidence, measurement and corporate responsibility.
Author:
Rubén Pérez Ramón Senior PLN Specialist
Sigma Cognition
LinkedIn
Leave a Reply